

Data Health Check
The goal of this health check is to ensure the integrity, availability, and performance of your data on your ARTESCA application. By proceeding to this proactive monitoring, it allows you to identify and anticipate potential data issues or bottlenecks that can occur.
To perform a data health check, follow this workflow:
Checking Alerts
In the ARTESCA UI, open the Alerts menu. A healthy system does not have any Critical Alerts or Warnings. If you only see the watchdog notification, your system is in a good state.

For more information on alerts, refer to Alert Management.
Monitoring the Storage Services Menu
To access this menu, in the ARTESCA UI, click Storage Services. This page displays high level information about your ARTESCA platform and its nodes.
Check the following elements to monitor your data health:
Node Status
Disk Usage
Storage Capacity
Node Status
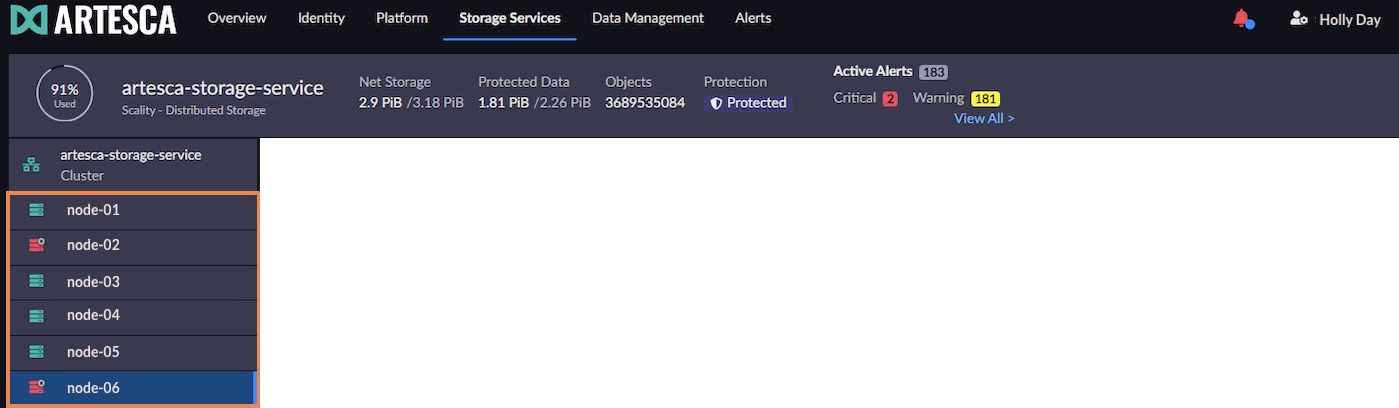
The ARTESCA UI provides high level information about a node status based on its icon color:
Green: the node is healthy.
Yellow: a warning is raised concerning the node.
Red: the node is not taking injection of data.
Check node statuses to ensure that your data are healthy.
When nodes are unable to take data, the system automatically redistributes the load among other healthy nodes. It guarantees continuous data availability and integrity.
Disk Usage
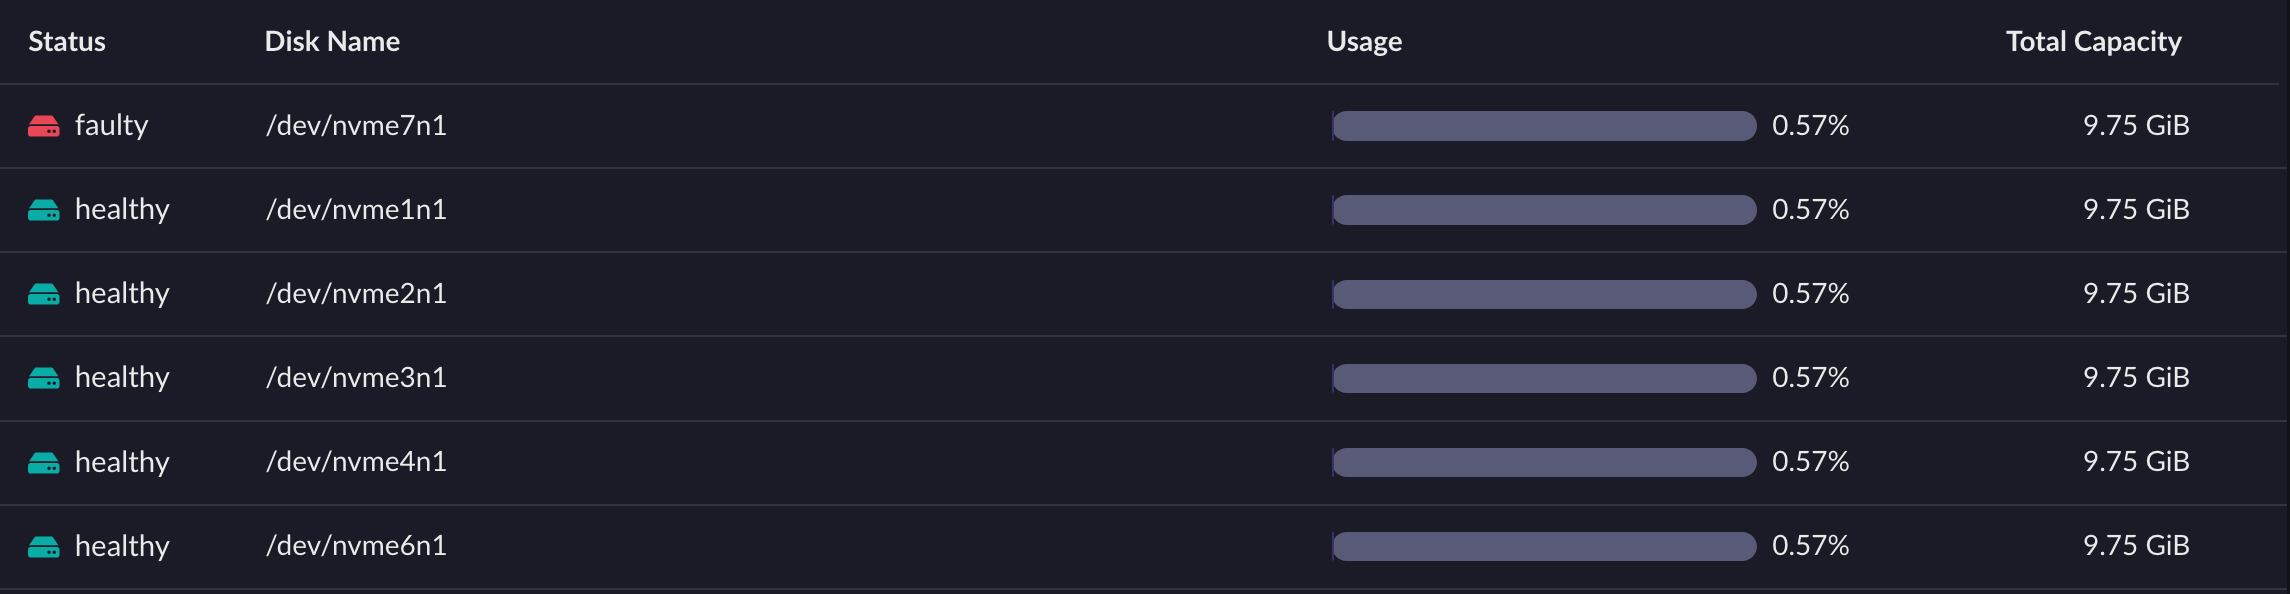
When clicking a storage node, you have access to a detailed view of disk usage. Each data disk is listed with its corresponding health status, disk name, usage percentage, and total capacity.
Monitor the graphical representation of usage to quickly identify data disks nearing full capacity.
To replace a data disk, refer to the disk replacement procedure.
Storage Capacity
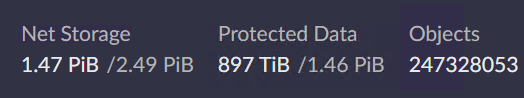
Checking the storage capacity allows you to better understand how data is stored on your ARTESCA platform.
Net Storage is the capacity used on disks. Its value is higher than Protected Data because it also includes the overhead induced by the network and the local data protection, as well as data that has not been relocated.
Protected Data is the capacity used by the application pushing data to ARTESCA. It is an estimation of the capacity available for storing protected data.
Objects is the number of objects present in ARTESCA buckets, including MPU parts.
Tip
The protection tooltip explains your protection schema and overhead.
Monitoring the Relocation Dashboard
To access the relocation dashboard, refer to Relocation Monitoring.

Check the Storage usage dashboard. It is composed of the following values: available, used, and reclaimable (the occupied space on disks for relocation to free capacity).

Check that the queued relocations dashboards converge to zero. It provides insight on relocation activity. The number always grows each time massive deletion is received by the cluster.
Monitoring the Repair Dashboard
To access the repair dashboard, refer to Repair Monitoring.

Repairs are first attempted on local replicas. They are then attempted on network (multi-node) replicas.
Check the storage usage. Activity is observed after a disk failure. It should converge until the repair is done.
Check the network repair data. Activity is observed after transient node interruption. It should converge until repair is done.


