

Performance Health Check
The goal of this health check is to ensure that your ARTESCA application is operating efficiently and effectively. It assesses the overall performance of the system and its network. By proceeding to this proactive monitoring, it allows you to identify and anticipate potential performance issues or bottlenecks that can occur.
To perform a performance health check, follow this workflow:
Checking Alerts
In the ARTESCA UI, open the Alerts menu. A healthy system does not have any Critical Alerts or Warnings. If you only see the watchdog notification, your system is in a good state.

For more information on alerts, refer to Alert Management.
Monitoring the S3 Service Dashboard
There are 4 important metrics to monitor your system performance:
S3 throughput
S3 latency
Average object size
Active requests
To access the S3 Service Dashboard, refer to S3 Service Monitoring.
S3 Throughput
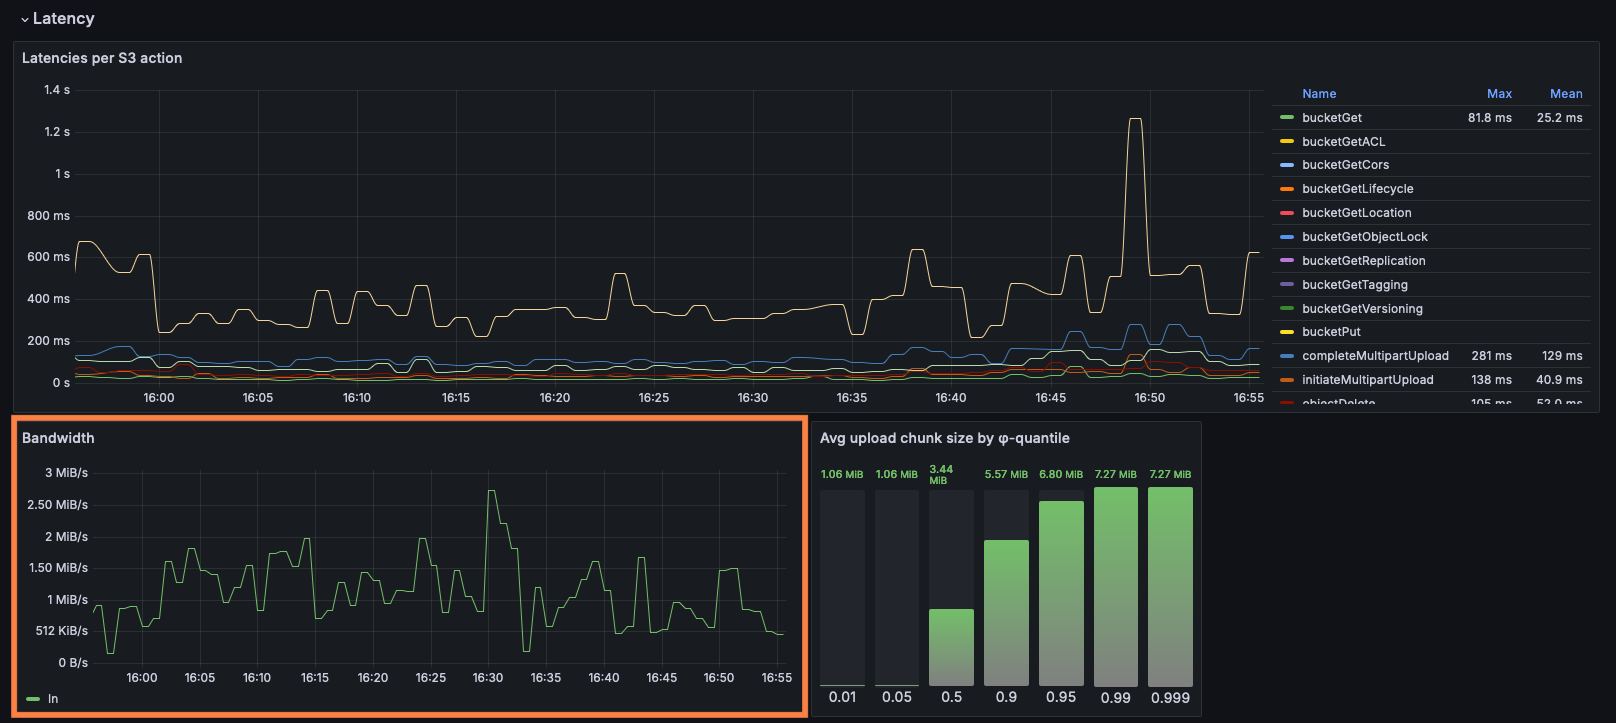
This metric provides an understanding of how much the sum of application on ARTESCA sends in terms of output.
Check the Ingestion bandwidth and the Read bandwidth.
Note
Low data indicates that the client is not sending much data.
S3 Latency
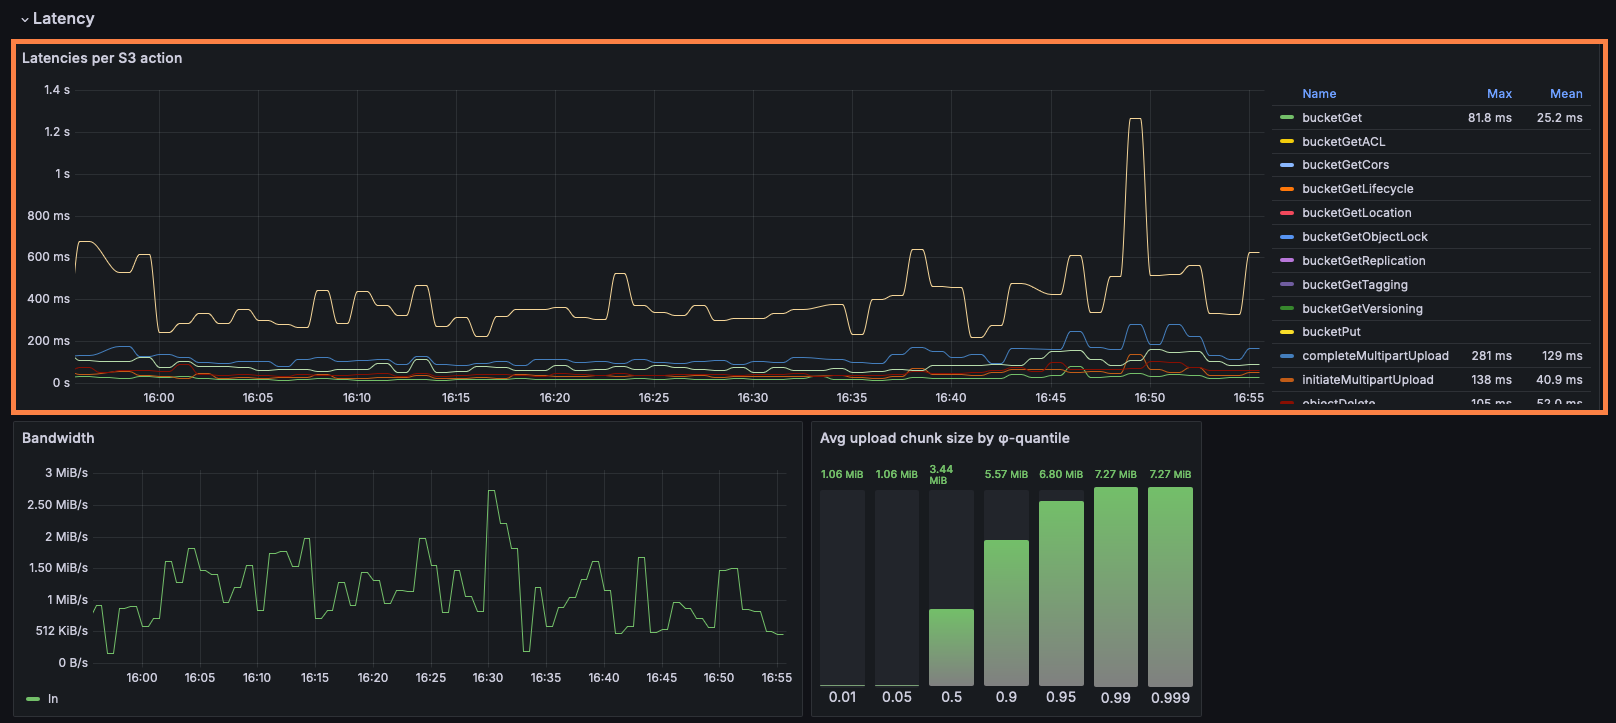
This metric is based per S3 call. Some features, such as MultiObjectDelete, can create high latency when running ingestion.
Check that its value is below 1 second of latency.
Average Object Size
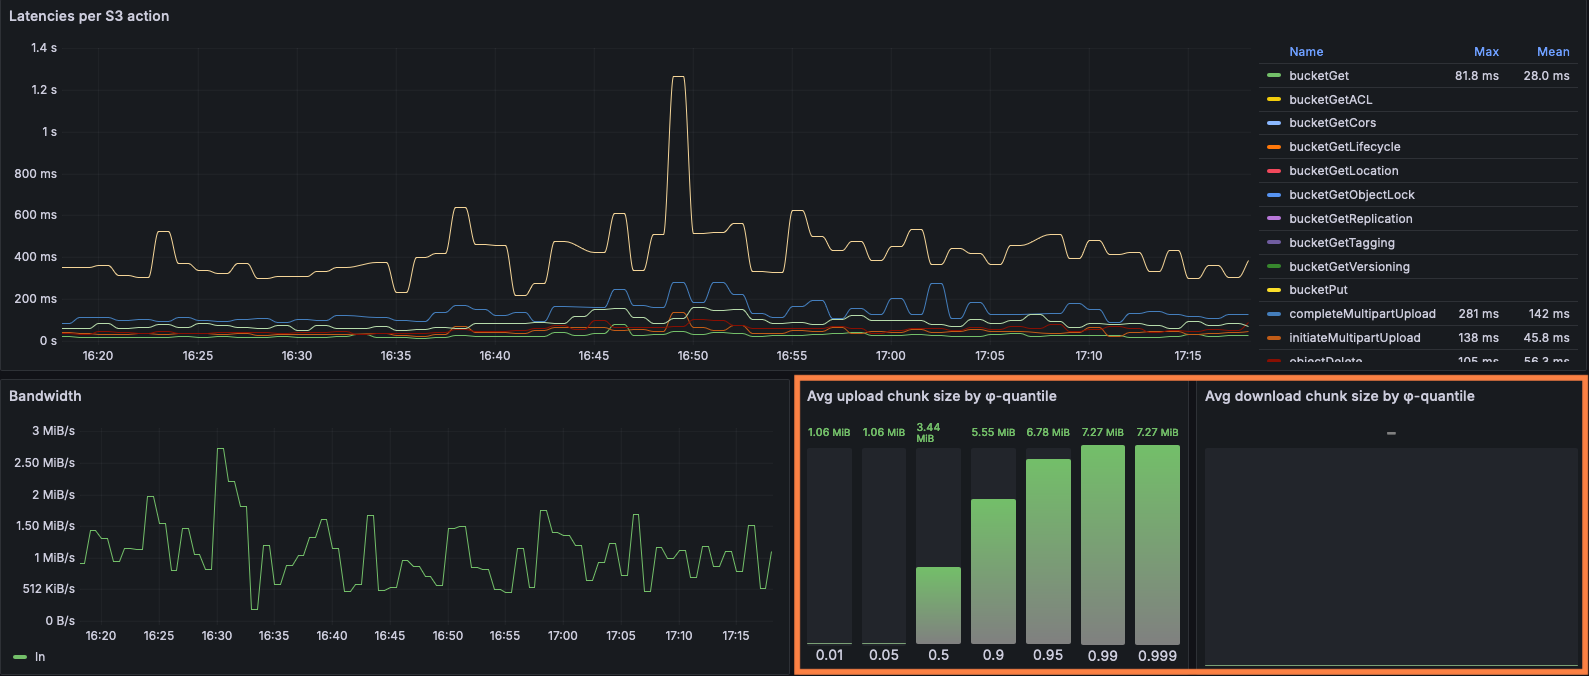
This metric provides information on the workload average object size. The throughput is better when the average object size is higher. The average object size can be calculated by taking the ratio of Protected Data (TiB) to the total number of objects from the Storage Service page.
Active Requests
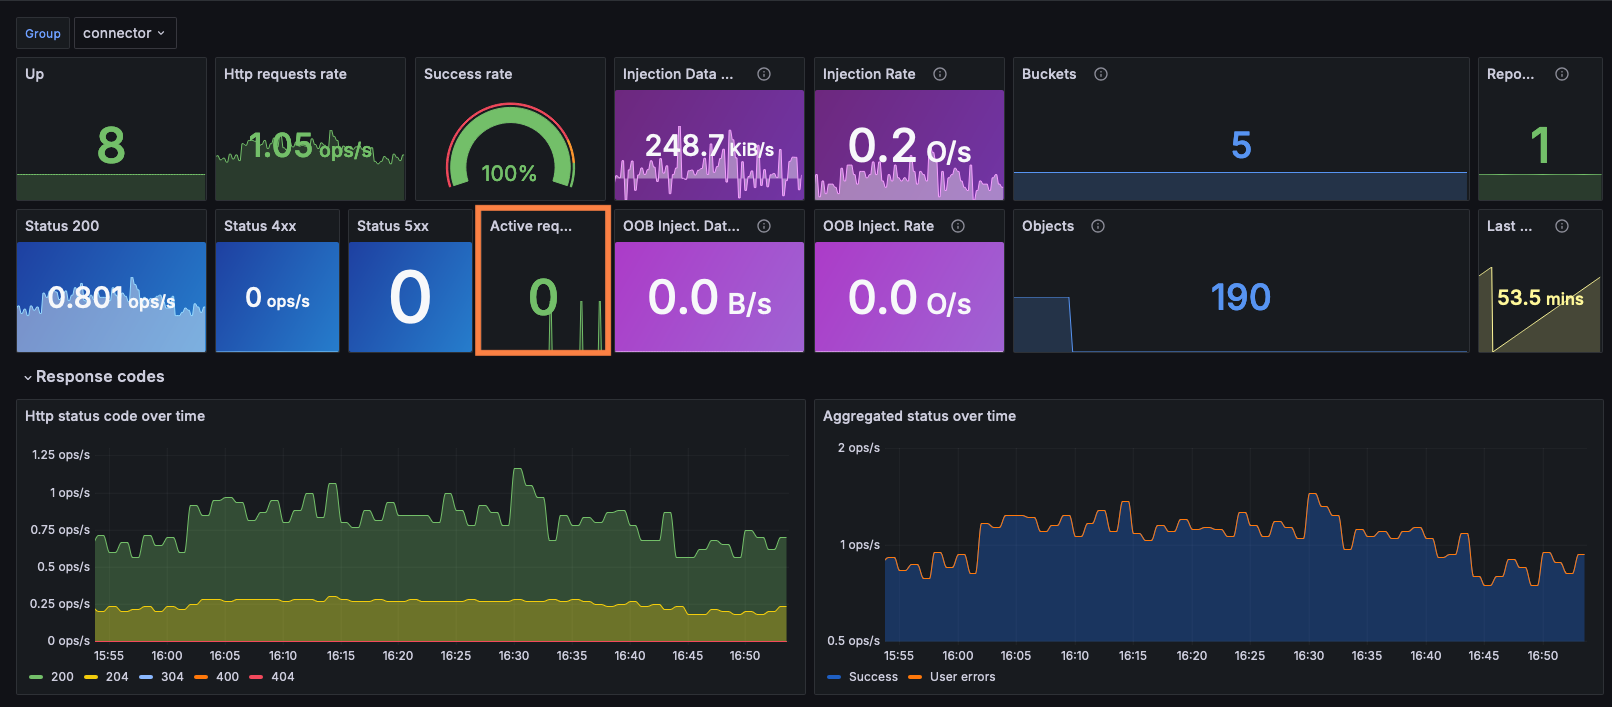
This metrics provides an understanding of the number of active requests handled by the ARTESCA application. The number depends on how much the client application is sending requests in parallel to the ARTESCA cluster.
Note
Several hundred requests can be handled simultaneously.
Monitoring the Platform Menu
To monitor the Platform menu gives you a high-level overview of the system’s performance.
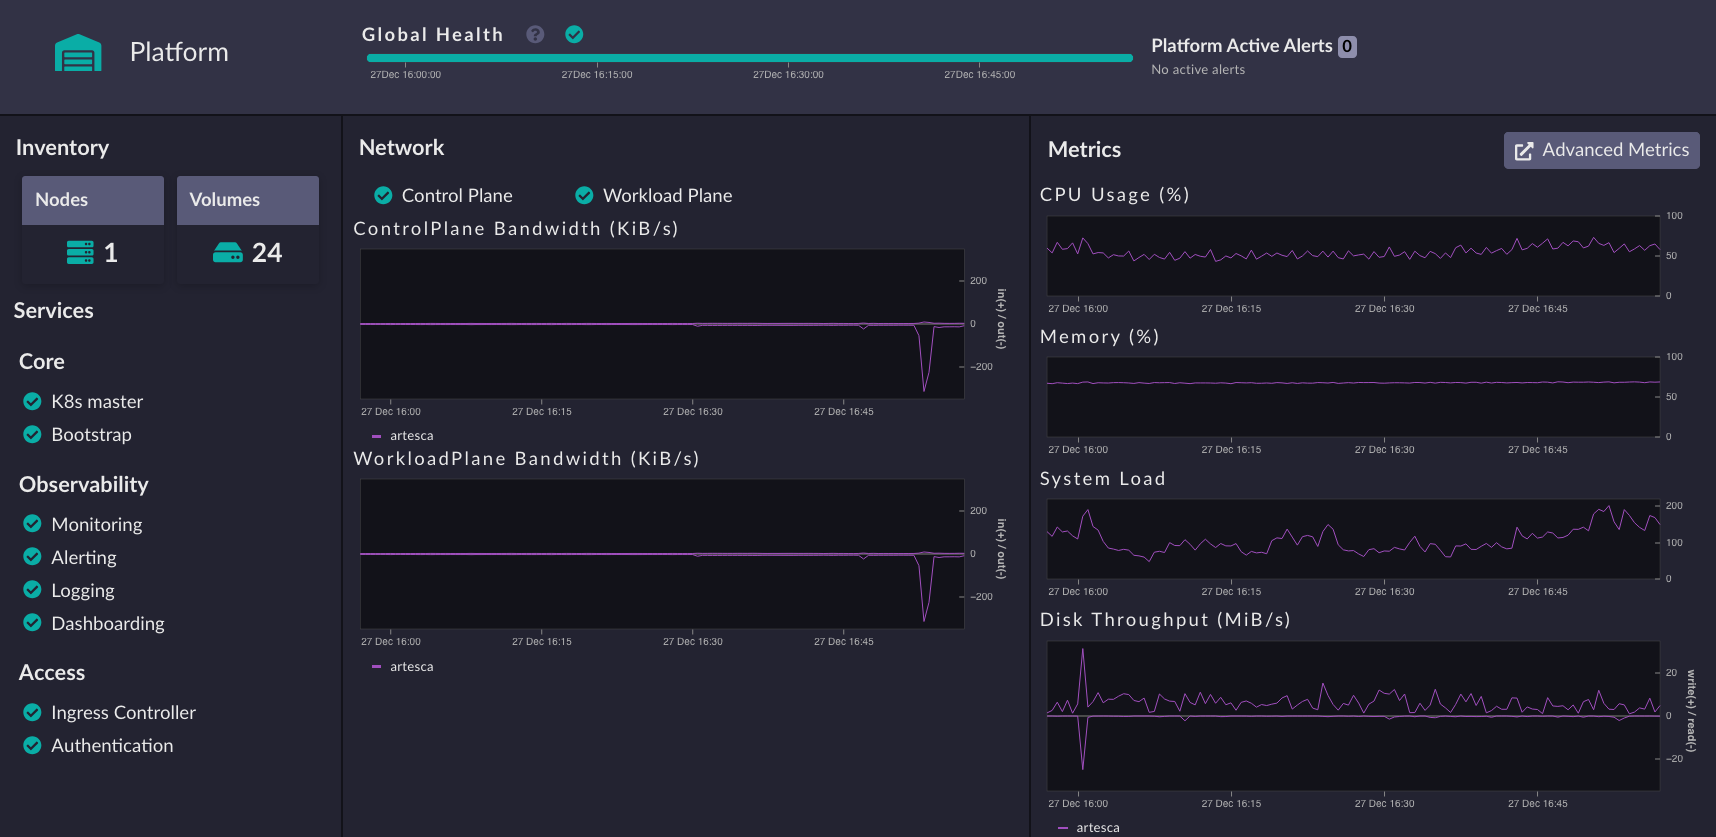
To access this Platform menu, in the ARTESCA UI, click the Platform menu. The Dashboard page displays general data to monitor:
Network metrics
System metrics
Network Metrics
The Network section is composed of the ControlPlane Bandwidth and Workload Plane Bandwidth.
Note
If not segregated, the ControlPlane Bandwidth and Workload Plane Bandwidth are almost similar.
The ControlPlane Bandwidth is anything related to operations in the UI or related to signalization between different nodes. It is always very low when the two networks are segregated.
The Workload Plane Bandwidth is the traffic coming from the application to ARTESCA and/or the different ARTESCA nodes. It should not be saturated as the network interfaces bandwidth have 2 x 10 Gbps LACP. If the network is saturated, spread backups and workloads over the day.
System Metrics
The system metrics corresponds to the Metrics section.
The System Load must not be continuously over 50. It indicates that the platform is overloaded.
The Memory must always be below 90%.
The Disk Throughput indicates the quantity of read and write data for each node.
Monitoring Individual Volume Performance
You can monitor the performance of an individual volume. An ARTESCA volume is either a data drive or a Metadata volume hosted on the NVMe Service Disk.

To access the metrics of a volume, refer to Volumes Monitoring.
For each volume, check the following elements:
The Usage should be below 90%.
The Disk Latency of a data disk is calculated in milliseconds. For a service disk, it is calculated in microseconds.
The Disk Throughput should be above 50 MB/s.
Note
High latency and low throughput can impact the overall S3 performance and require deeper analysis of disks or service disk performance. Contact Scality support for further assistance.


