

ARTESCA Storage Service Disks are Disabled
Problem Description
An alert reporting that the cluster is unavailable displays in the Alerts tile of the Overview page.
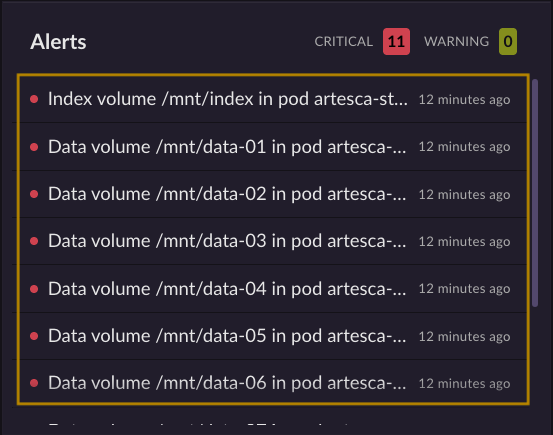
For more information about the alert, open the Alerts menu.
Root Cause
One or more disks have been disabled due to an I/O error during a write operation. This can be seen in the alerting dashboard.
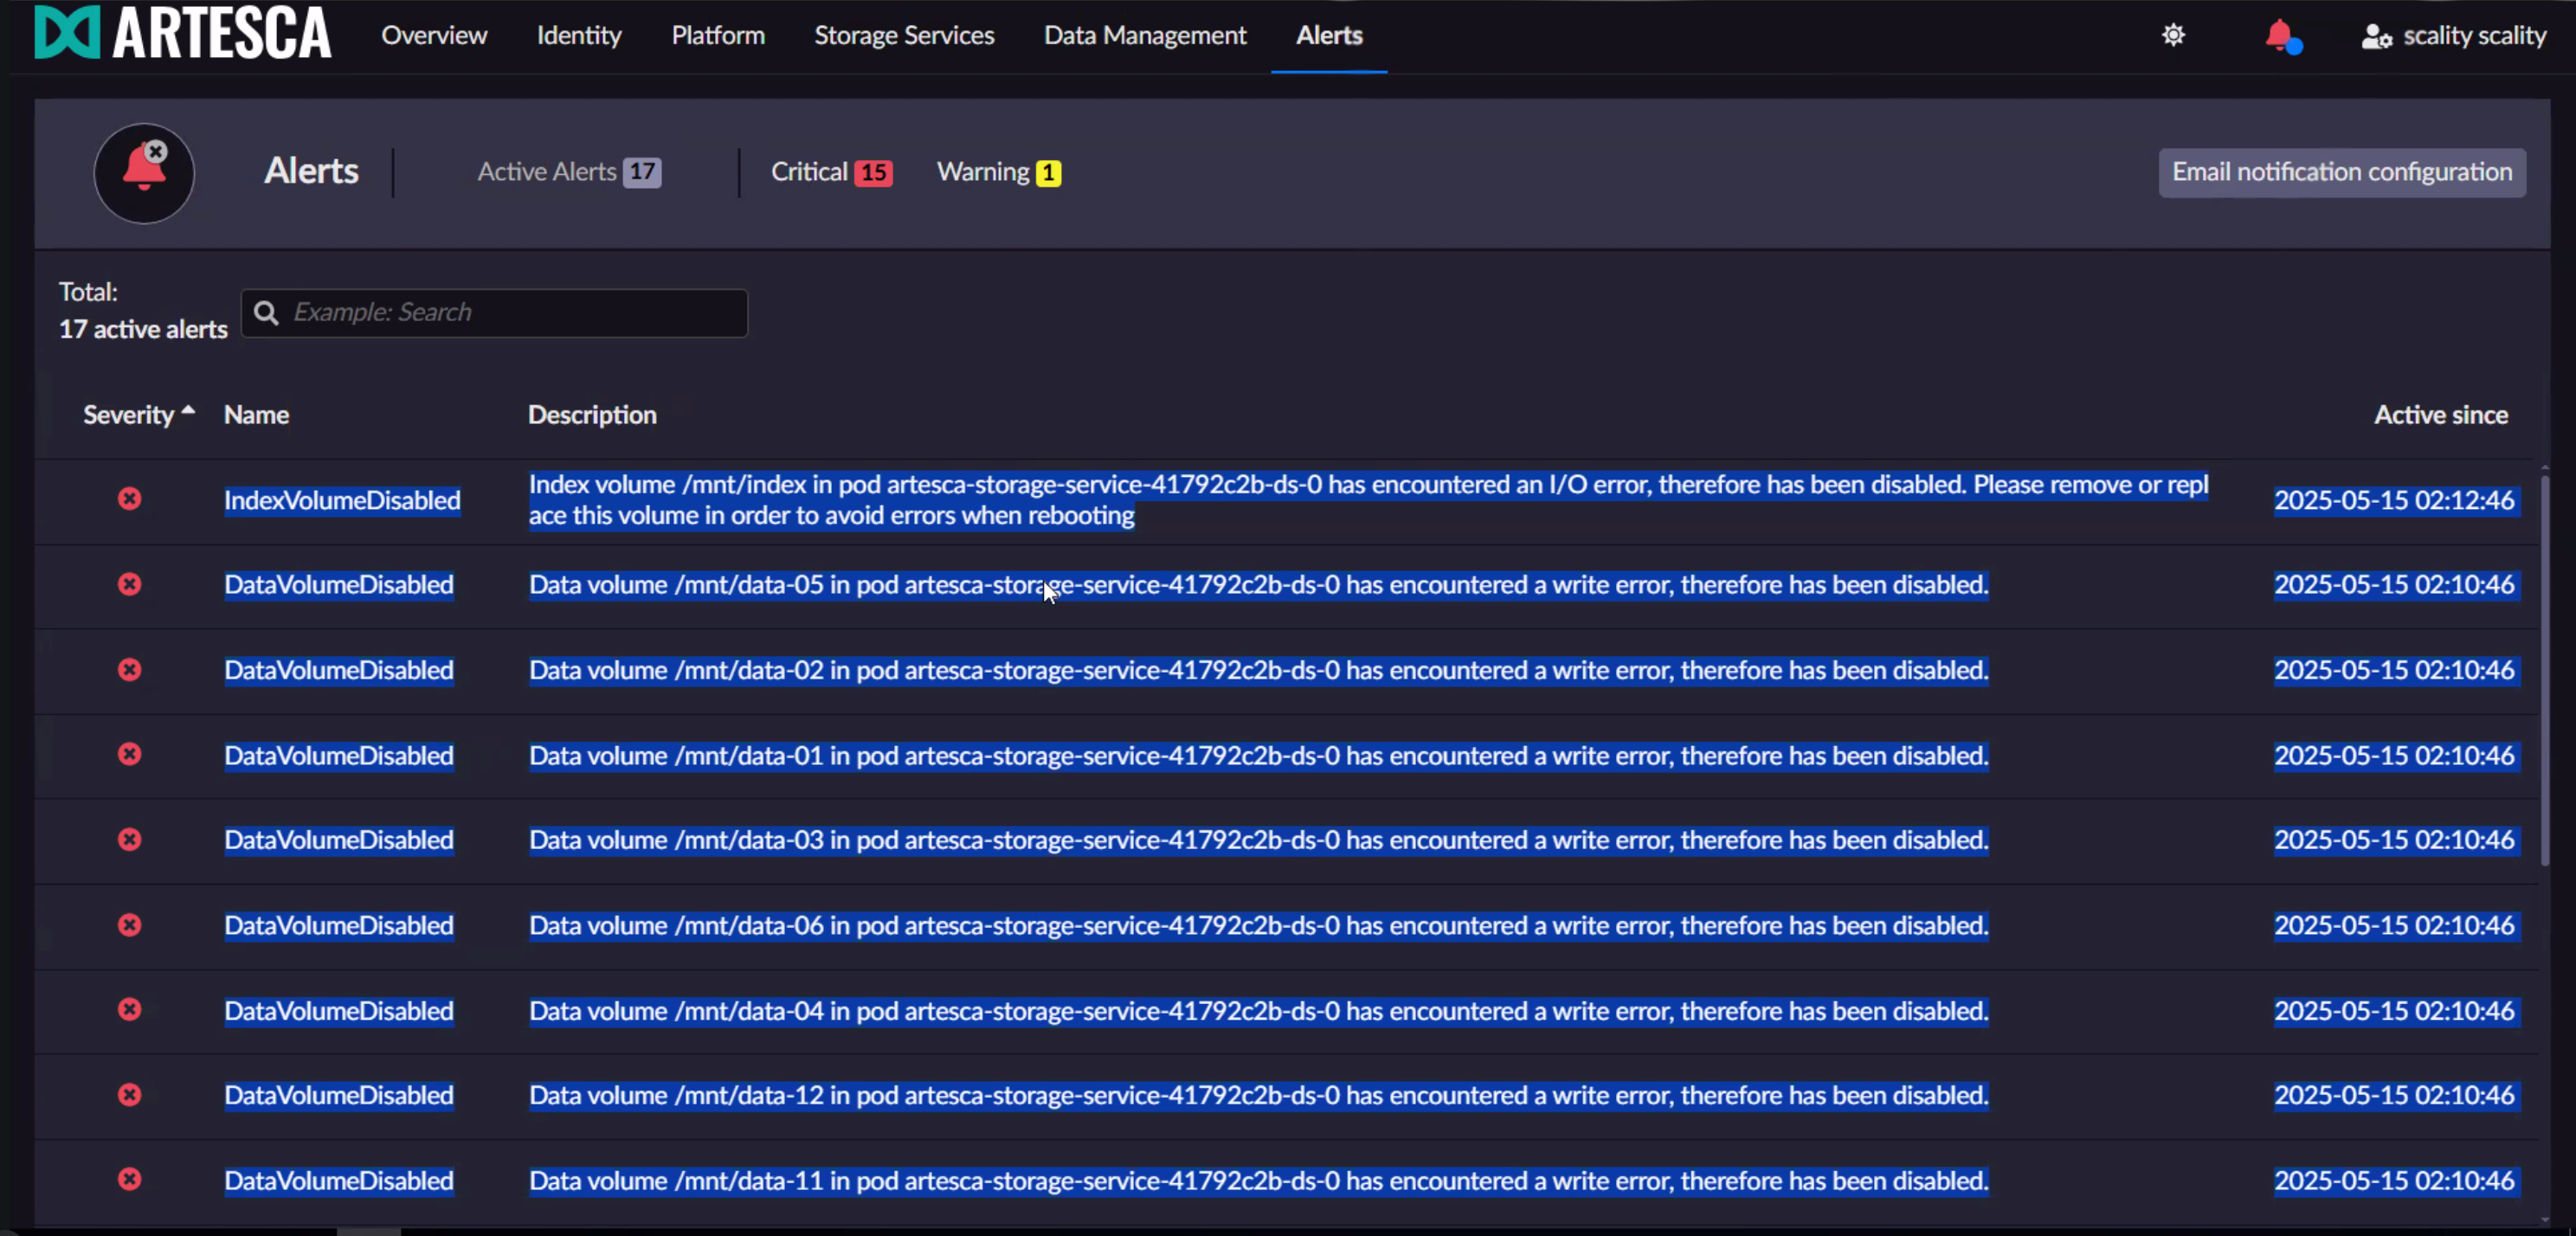
An I/O error during a write operation leads to disk deactivation and the data is rebuilt on the remaining healthy drives. This can be due to:
An unhealthy disk. In that case, you have to replace the faulty disk.
A temporary loss of connectivity to the disk, due to a RAID card failure. One of the symptoms of the RAID card failure is that multiple disks are disabled at the same time, because usually multiple disks are connected to the same RAID card. In that case, you have to re-instate the disk. Contact Scality Support for assistance.
An I/O error during a write operation can indicate an intermittent connectivity issue to the underlying storage. In that case, the drive is temporarily deactivated, but the data is not rebuilt on the remaining drives. The administrator can check that the write I/O error has been transient, and then re-activate the drive, or deactivate it permanently by following the procedure below.
Investigation Steps
Check the health of the physical disks, and their connectivity to the virtual machine.
To view all disabled disks from a node (with a red status):
Click the Storage Services menu.
Click the node name in the left panel to view its disks.
Disabled disks (with a red status) will appear at the top of the disk list for that node.
Note the node name and disk device name for each disabled disk that needs to be re-enabled.
Problem Resolution
Before proceeding with the following procedure, ensure that:
Disks are healthy and properly connected.
Your system is deployed with a Virtual Machine profile.
Identify the name of the node and the disk name.
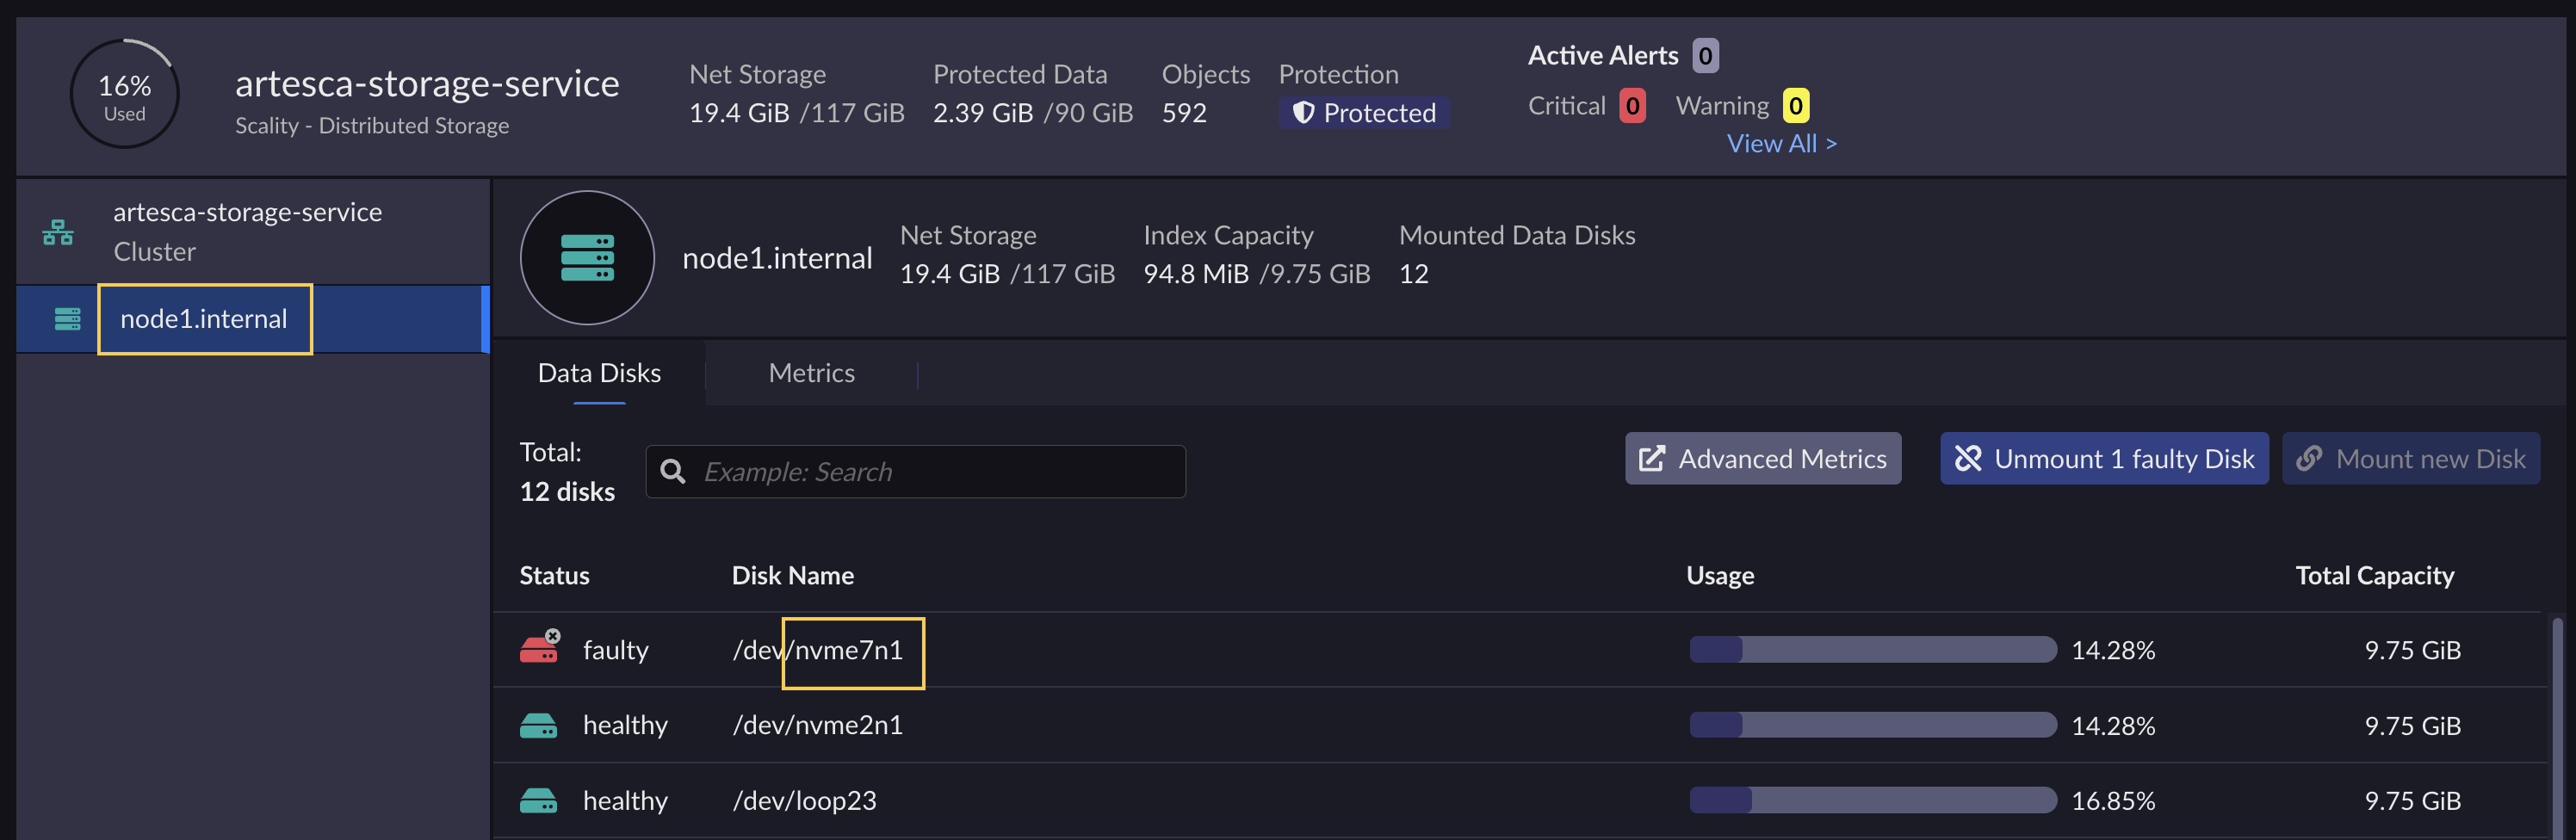
Here, the identified node name is
node1.internaland the disk name isnvme7n1.Generate the script to enable the disk.
[artesca-os@bootstrap ~]$cat > enable_disk_vm.sh << 'EOF' #!/bin/bash # Script to map a disk device to its storage service volume name for repair # Usage: ./enable_disk_vm.sh <node_name> <disk_device> # Example: ./enable_disk_vm.sh node1.example.com sda set -e # Check if parameters are provided if [[ $# -ne 2 ]]; then echo "Usage: $0 <node_name> <disk_device>" echo "Example: $0 node1.example.com sda" exit 1 fi NODE_NAME=$1 DISK_TO_REPAIR=$2 # Set KUBECONFIG for all kubectl commands export KUBECONFIG=/etc/kubernetes/admin.conf # Find dataservice by node name DATASERVICE=$(sudo kubectl -n xcore get dataservices -o jsonpath='{range .items[*]}{.spec.nodeName}___{.metadata.name}{"\n"}{end}' | grep "${NODE_NAME}___" | awk -F'___' '{print $2}') if [[ -z "$DATASERVICE" ]]; then echo "Error: Could not find dataservice for node $NODE_NAME" echo "Available node to dataservice mappings:" sudo kubectl -n xcore get dataservices -o jsonpath='{range .items[*]}{.spec.nodeName} -> {.metadata.name}{"\n"}{end}' exit 1 fi # Step 1: Get Metalk8s volume name for device VOLUME=$(sudo kubectl get volumes -o jsonpath='{range .items[*]}{.status.deviceName}___{.metadata.name}{"\n"}{end}' | grep "${DISK_TO_REPAIR}___" | awk -F'___' '{print $2}') if [[ -z "$VOLUME" ]]; then echo "Error: Could not find Metalk8s volume for device $DISK_TO_REPAIR" echo "Available devices:" sudo kubectl get volumes -o jsonpath='{range .items[*]}{.status.deviceName}{"\n"}{end}' | sort | uniq exit 1 fi # Step 2: Get PVC name from Metalk8s volume PVC=$(sudo kubectl -n xcore get pvc -o jsonpath='{range .items[*]}{.spec.volumeName}___{.metadata.name}{"\n"}{end}' | grep "${VOLUME}___" | awk -F'___' '{print $2}') if [[ -z "$PVC" ]]; then echo "Error: Could not find PVC for Metalk8s volume $VOLUME" exit 1 fi # Step 3: Get xcore volume name from StatefulSet STATEFULSET_NAME="${DATASERVICE}-ds" XCORE_VOLUME=$(sudo kubectl -n xcore get statefulset "$STATEFULSET_NAME" -o jsonpath='{range .spec.template.spec.volumes[*]}{.persistentVolumeClaim.claimName}___{.name}{"\n"}{end}' | grep "${PVC}___" | awk -F'___' '{print $2}') if [[ -z "$XCORE_VOLUME" ]]; then echo "Error: Could not find xcore volume name for PVC $PVC in StatefulSet $STATEFULSET_NAME" echo "Available PVC mappings in StatefulSet:" sudo kubectl -n xcore get statefulset "$STATEFULSET_NAME" -o jsonpath='{range .spec.template.spec.volumes[*]}{.persistentVolumeClaim.claimName} -> {.name}{"\n"}{end}' exit 1 fi # Enable the disabled disk sudo kubectl -n xcore exec -i -t $DATASERVICE-ds-0 -- /usr/bin/enable_disabled_disk $XCORE_VOLUME EOF
Run the script.
[artesca-os@bootstrap ~]$chmod +x enable_disk_vm.sh ./enable_disk_vm.sh node1.internal nvme7n1
If successful, the script output must look like the following.
Output example¶data-XY is disabled, this script will enable it enabling data-XY done
Repeat this procedure for each disabled disk that needs to be re-enabled.
Note
If you have multiple disabled disks, you will need to run the script for each one separately, using the appropriate node name and disk device name for each disk.


